GPU Cloud India
for AI & HPC — Deploy in Seconds
NVIDIA RTX 6000 Ada, L4 GPU & RTX 6000 Blackwell — hosted inside India. Train LLMs, run inference, render, HPC. DPDP compliant. INR billing, no forex risk.
India-Ready AI GPU Cloud, High Performance & Scalability
Dedicated GPU instances powered by AMD EPYC processors and NVIDIA accelerators with enterprise NVMe storage in Tier III+ Indian data centers.
Platinum Cloud GPU
India-Ready AI Cloud Server Solutions
What You Will Get
- AMD EPYC 16 Core Processor
- 64 GB Ram
- 24 GB GPU Memory
- 1 TB NVME Storage
L4 AMD EPYC 9015
India-Ready AI Cloud Server Solutions
What You Will Get
- AMD EPYC 9015 8Core, 16vCPU processor
- 64 GB DDR5 Ram
- L4 24 GB GPU Memory
- 480 GB NVME Disk
Titanium Cloud GPU
India-Ready AI Cloud Server Solutions
What You Will Get
- AMD EPYC 32 Core Processor
- 128 GB Ram
- L4 48 GB GPU Memory
- 2 TB NVME Storage
L4 Dual AMD EPYC 9015
India-Ready AI Cloud Server Solutions
What You Will Get
- Dual AMD EPYC 9015 16Core, 32vCPU processor
- 128 GB DDR5 Ram
- L4 48 GB GPU Memory
- 960 GB NVME Disk
Not just GPUs.
A full AI platform.
Multi-GPU clusters, distributed training, model serving, storage — everything to go from experiment to production.
Scale from 1 to 8 GPUs per node. NVLink for high-bandwidth GPU-to-GPU communication. InfiniBand networking for multi-node distributed training.
Deploy production LLM endpoints with vLLM, TGI, or TRT-LLM. Auto-scaling replicas, A/B testing, model versioning, and sub-10ms latency for India users.
End-to-end ML pipeline management. Kubeflow, MLflow experiment tracking, Jupyter Hub, dataset versioning, automated retraining — India-hosted.
NVMe local storage for hot data, distributed NFS for shared datasets, and S3-compatible object storage for model checkpoints — all in India.
Save up to 70% with spot GPU pricing for fault-tolerant training jobs. Automatic checkpoint integration ensures no work is lost on preemption.
GPU-enabled Kubernetes clusters with NVIDIA device plugins, GPU operator, and Helm chart marketplace. Auto-scale your AI workloads dynamically.
What will you
build on India's GPU?
LLM Training & Fine-tuning in India
MULTI-GPU · NVLINKTrain or fine-tune large language models — Llama, Mistral, Gemma, Falcon, or your custom architecture — on India's NVIDIA RTX 6000 Ada, L4 GPU, and RTX 6000 Blackwell clusters. High-bandwidth interconnects ensure maximum GPU-to-GPU performance. All training data stays in India, meeting DPDP requirements for Indian AI companies.
Train in India.
Serve in India.
Major GPU hyperscalers (AWS, Azure, GCP) don't offer their latest GPUs in Indian regions. You'd send data to Singapore or the US — adding 100–200ms latency and violating data residency laws. CloudTechTiq runs RTX 6000 Ada, L4 GPU, and RTX 6000 Blackwell inside India.
CloudTechTiq vs India GPU competitors.
E2E Networks, NeevCloud, DigitalOcean — how do they really compare?
| Feature | CloudTechTiq ✦ | E2E Networks | NeevCloud | DigitalOcean |
|---|---|---|---|---|
| RTX 6000 GPU in India | ✓ | ✓ | ✓ | ✗ |
| Fully Managed GPU | ✓ | Self-service | Self-service | Self-service |
| INR Billing + UPI | ✓ | ✓ | ✓ | USD only |
| Mumbai + Noida DCs | Both | Multi-zone | Indore only | Bangalore only |
| MLOps Platform (Managed) | ✓ | ✗ | ✗ | ✗ |
| VPS + Dedicated + GPU | All three | GPU + VPS | GPU only | VPS + GPU |
| Office 365 / Azure Managed | ✓ | ✗ | ✗ | ✗ |
| DPDP Act Compliance Advisory | ✓ | Infra only | Infra only | ✗ |
| 24/7 India Support Team | ✓ Human | Ticket | Ticket | No India team |
Frequently Asked Questions
What NVIDIA GPUs are available in India?+
How much does GPU cloud cost in India?+
How is CloudTechTiq different from E2E Networks for GPU?+
Can I train LLMs on your GPU cloud?+
Does GPU data stay in India?+
What is a spot GPU instance?+
High-Performance Servers —
built for demanding workloads.
How to Optimize GPU Servers for Deep Learning Applications
Deep learning has transformed fields such as computer vision, natural language processing,
Read article →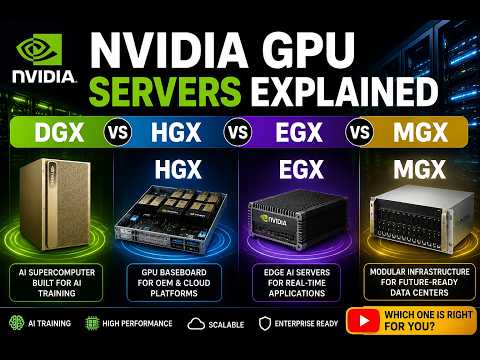
NVIDIA GPU Servers Explained | DGX vs HGX vs EGX vs MGX
we explain NVIDIA GPU server platforms, including DGX, HGX, EGX, and MGX, in simple
Watch video →
Remote Desktop with Hardware Acceleration on GPU Servers Using Linux
In today’s fast-paced digital world, remote work, cloud computing, and AI-driven applications
Read article →